This note introduces the main proof in Chapters 3–6. The goal is to explain why a convex viscosity solution $u$ on an open convex domain $\Omega$ satisfying
The proof joins the dimension of supporting contact sets, the short axes of John ellipsoids, volume decay of strict sections, and Mooney’s covering theorem into one closed chain. The critical contact dimension is $q=n-k+1$.
For $x\in\Omega$ and $p\in\partial u(x)$, let $\ell_{x,p}$ be the corresponding supporting affine function. Write $d_u(x,p)$ for the stabilized affine dimension, at small scales, of the local contact set $\{u=\ell_{x,p}\}$. Define
$$C_m(u)=\left\{x:d_u(x,p)\ge m\ \text{for every }p\in\partial u(x)\right\}.$$
The words “for every supporting slope” are essential because the covering theorem in Chapter 6 requires volume decay for every section at the point.
Chapter 3: if one supporting slope has contact dimension at most $n-k$, then $u$ is smooth nearby.
Chapter 4: positive $k$-Hessian density controls the product of the shortest $k$ axes of the John ellipsoid of a small sublevel set.
Chapter 5: $m$-dimensional contact and quadratic localization together give $|S_h|\lesssim h^{(m+k)/2}$.
2. First engine: small contact sets imply local smoothness
The approximation, interior second-derivative estimate, and Evans–Krylov steps are standard; the device that actually starts the argument is a saddle surface. After subtracting a supporting affine function, normalize $u(0)=0$ and $u\ge0$. Suppose $\{u=0\}$ lies in a subspace $Z$ of dimension at most $n-k$ in a small ball. Split $\mathbb R^n=Y\oplus Z$. Then $\dim Y\ge k$; choose $k$ directions in $Y$ and construct
$$Q(y,z)=A|y|^2-|z|^2+\alpha r^2.$$
The two families of directions have opposite but complementary jobs. At least $k$ strongly positive curvatures in $Y$ ensure $D^2Q\in\Gamma_k$, while the negative curvature along the contact space $Z$ pushes $Q$ below $u$ on the spherical boundary. Choosing $A$ and $\alpha$, then scaling, gives both $Q<u$ on the boundary and $Q>u$ near the center. A purely convex paraboloid cannot provide this geometry.
For smooth $k$-admissible CNS approximations $u_j$, choose a regular value $t_j$ and take the component containing the origin of
$$D_j=\{Q-u_j>t_j\}.$$
The boundary/center sign change traps $D_j$ inside the small ball, and the regular value gives a smooth moving boundary. The localized Chou–Wang estimate then yields a Hessian bound independent of $j$ on $D_j$. Evans–Krylov for the concave operator $F=\sigma_k^{1/k}$, followed by Schauder estimates, yields local smoothness of the limit $u$.
Uniform convergence $u_j\to u$ does not by itself produce a $C^2$ limit. The genuine regularizing step is the moving domain cut out by the saddle surface together with the Chou–Wang Hessian estimate.
图1。 马鞍面的两个方向:接触方向中的负曲率负责封住边界,至少 $k$ 个横向正曲率负责保持 $k$-admissibility。图面可用鼠标拖动旋转,并用滚轮缩放。Figure 1. The two directions of the saddle surface: negative curvature in the contact directions closes the boundary, while at least $k$ positive transverse curvatures preserve $k$-admissibility. Drag to rotate and use the wheel to zoom.
3. Second engine: John ellipsoids and an interior viscosity test
The strict section $K_h=\{u\le h\}\cap\overline B_R$ is convex, but its boundary may be complicated, its principal directions may rotate with scale, and its directional sizes may be wildly different. The proof does not assume that the section itself is an ellipsoid. John’s theorem compresses this geometric complexity into one inscribed ellipsoid, hence $n$ semiaxes and their principal directions:
Order the semiaxes of $A_h$ as $a_1\ge\cdots\ge a_n$. Up to the fixed dimensional factor $n$, the full convex-geometric complexity of the section has now become bookkeeping for these $n$ ordered axes. Construct the test function
$$P_h(x)=h\left|A_h^{-1}(x-z_h)\right|^2.$$
Set $\mu_h=\min(P_h-u)$. The translate $P_h-\mu_h$ touches $u$ from above at an auxiliary interior point $y_h$. Since $D^2P_h=2hA_h^{-2}>0$, the viscosity inequality gives
This is an upper bound for the product of the shortest $k$ John axes. The equation controls their product, not each axis separately.
图2。 第4章内部黏性测试的几何结构。抬高平面显示 graph cap;$K_h$ 与 $E_h$ 位于自变量空间,测试点 $y_h$ 由最小化 $P_h-u$ 自动产生。Figure 2. The geometry of the interior viscosity test in Chapter 4. The lifted plane displays the graph cap; $K_h$ and $E_h$ lie in the variable space, and $y_h$ is generated by minimizing $P_h-u$.
4. 第三个引擎:接触维数与 section 体积
这一节的核心不是把 $K_h$ 想象成某个规则形状,而是把上一节得到的有序 John 轴分成三段。记 $q=n-k+1$。测试函数与黏性方程给出最短 $k$ 根轴的乘积上界
4. Third engine: contact dimension and section volume
The point is not to imagine $K_h$ as a regular shape, but to split the ordered John axes from the previous section into three ranges. Put $q=n-k+1$. The test function and viscosity equation give the product bound for the shortest $k$ axes,
$$a_q\cdots a_n\lesssim \lambda^{-1/2}h^{k/2}.$$
On the other hand, if the supporting contact set contains a relative $m$-ball of radius $\rho$, the upper John inclusion and a width min-max argument give $a_m\gtrsim\rho$. Since $a_1\ge\cdots\ge a_n$, this means
$$a_1,\ldots,a_m\gtrsim\rho.$$
When $m\ge q$, the two index ranges genuinely overlap: $a_q,\ldots,a_m$ belong both to the contact-lower-bound range and to the PDE-controlled product. Dividing these overlap factors out of the short-axis product yields
This forces rapid collective decay of the shortest $n-m$ axes after the overlap. A gap remains: the first $m$ axes have lower bounds but may still be arbitrarily long, so the last display alone does not control the volume of the whole section. The repair is to set
$$v(x)=u(x)+\frac{|x|^2}{2}.$$
Adding this smooth quadratic leaves the singular set unchanged: $u$ is locally $C^2$ at a point if and only if $v$ is. The $k$-Hessian equation is not applied to $v$; every PDE product estimate still comes from $u$. The quadratic term is used only for geometric localization. For the corresponding strict section, $v(x)\le h$ implies $|x|^2/2\le h$, hence
$$S_h^v\subset K_h\cap B_{\sqrt{2h}}.$$
This smooth lift truncates all potentially long first $m$ contact directions to $O(\sqrt h)$, contributing $h^{m/2}$; the remaining short-axis product after cancellation contributes $h^{k/2}$. Combining the two pieces gives
图3。 半轴按 $a_1\ge\cdots\ge a_n$ 排列。上括号覆盖 $q\le i\le n$,下括号覆盖 $1\le i\le m$,所以 $q\le i\le m$ 是两种控制的重合区间;着色的 $m+1\le i\le n$ 正是消去重合后要处理的短轴。Figure 3. Order the semiaxes as $a_1\ge\cdots\ge a_n$. The upper brace spans $q\le i\le n$ and the lower brace spans $1\le i\le m$, so $q\le i\le m$ is their overlap; the shaded range $m+1\le i\le n$ contains the short axes left after cancellation.图4。 Proposition 5.1 的几何顺序:接触片、$K_h$、John 轴下界以及 $S_h^v\subset K_h\cap B_{\sqrt{2h}}$。Figure 4. The geometric order in Proposition 5.1: the contact patch, $K_h$, the John-axis lower bound, and $S_h^v\subset K_h\cap B_{\sqrt{2h}}$.
The covering theorem allows the constants and height thresholds to depend on $(x,p)$, so the absence of a uniform lower bound for the contact radius $\rho$ does not obstruct the argument. Full-dimensional contact, on the other hand, would produce an upper quadratic test of arbitrarily small curvature, contradicting $\sigma_k\ge\lambda$. Hence $C_n(u)=\varnothing$.
Chapter 3 gives $\operatorname{Sing}(u)\subset C_q(u)$. Applying the stratification result at $m=q=n-k+1$ yields $\mathcal H^{n-1}_{\mathrm{loc}}(\operatorname{Sing}(u))=0$.
Here $q=2$. On the critical stratum $m=2$, contact geometry gives $a_2\gtrsim\rho$, while the PDE gives $a_2a_3a_4\lesssim h^{3/2}$. After adding the quadratic term,
图5。 $n=4$、$k=3$ 时,$m=2$ 与 $m=3$ 两层的 John 轴乘积、section 体积指数和 Hausdorff 指数。Figure 5. For $n=4$ and $k=3$, the John-axis products, section-volume exponents, and Hausdorff exponents on the $m=2$ and $m=3$ strata.
$k=n$: $q=1$ and the conclusion recovers the Monge–Ampère stratification $\mathcal H^{n-m}(C_m)=0$.
$k=2$: this method gives codimension-one nullity for the critical contact stratum; full smoothness needs the additional input of strict $2$-convexity.
Axis control: the equation controls only a product of short axes. Principal directions may rotate and redistribute with scale, so the conclusion is Hausdorff nullity rather than a uniform Minkowski packing estimate.
关于本文。 这是一篇介绍 Xiyu Hu, Sharp Hausdorff Bounds for the Interior Singular Set of Convex k-Hessian Solutions 第3–6章的证明导读 note。论文第8章的 mean-value 公式提供概念动机,但不作为上述主证明链的输入。
About this note. This is a proof-guide note to Chapters 3–6 of Xiyu Hu, Sharp Hausdorff Bounds for the Interior Singular Set of Convex k-Hessian Solutions. The mean-value formula in Chapter 8 provides conceptual motivation but is not an input to the proof chain above.
Two extremal problems can share a proof architecture without sharing a proof. Benjamin Bedert’s 2025 breakthrough on large sum-free subsets is additive and Fourier-analytic. A July 2026 manuscript on strongly $2$-primitive sets is multiplicative and hypergraph-theoretic. Their common language is not a transferable sieve, but a four-step design: localize, build a strong object in each local block, prevent leakage between blocks, and add the gains. That comparison points toward the right stability question – and also reveals why the most naive version of stability is false.
Status and scope. Bedert’s theorem is the February 2025 arXiv preprint cited below. The $27/2$ theorem is contained in a five-page manuscript by Przemek Chojecki supplied for this post in July 2026; no public preprint or peer-reviewed version was found, and the Erdős Problems page for #793 still labels the problem open at the time of writing. The written proof was checked here for internal coherence, but that is not independent peer review. The factor-graph and normalized-stability results later in this article are the additional analysis developed in the accompanying long note. Conditional and open statements are labelled explicitly.
Here is the headline before the details. The supplied manuscript claims
where $F(n)$ is the largest size of a strongly $2$-primitive subset of $[1,n]$. One might expect every near-extremizer to be close to the construction behind this formula: almost all primes, plus products of three primes near $n^{1/3}$ arranged as a nearly saturated linear $3$-uniform hypergraph. That literal statement is false. There is, however, an exact and useful replacement: after contracting harmless private-prime lifts, every near-extremizer has a canonical prime layer and a small exceptional hub carrying the entire second-order excess. If the residual hub is mostly made of squarefree triples, then pair saturation and $n^{1/3}$-scale stability follow. Proving – or refuting – that triple-core hypothesis is the remaining inverse problem.
1. Two problems that look similar only from far away
1.1 The sum-free extraction problem
A set $B\subset\mathbb Z$ is sum-free if it contains no $x,y,z$, not necessarily distinct, with
$$x+y=z.$$
For a finite set $A$ of integers, write
$$
S(A)=\max\{|B|:B\subseteq A,\ B\text{ is sum-free}\},
$$
and, for $N$-element sets of positive integers,
$$
S(N)=\min_{|A|=N}S(A).
$$
This is an extraction problem. An adversary gives us an arbitrary host set $A$, and we must find a large structured subset inside it. Erdős’s middle-third argument gives $S(A)\ge |A|/3$. Alon and Kleitman improved this to $(N+1)/3$, and Jean Bourgain proved $S(N)\ge (N+2)/3$ in 1997. The long-standing qualitative question was whether the additive improvement can tend to infinity:
Bedert answered yes, proving that an absolute $c\gt0$ exists such that
$$
S(A)\ge \frac{|A|}{3}+c\log\log |A|.
$$
1.2 The strongly $2$-primitive packing problem
A set $A\subseteq[1,n]$ is strongly $2$-primitive when
$$
a\nmid bc
\qquad
(a,b,c\in A,\ a\notin\{b,c\}),
$$
where $b=c$ is allowed. The word strongly matters. Under a more recent convention, a $2$-primitive set only forbids witnesses $b,c$ that are distinct. For example, $\{4,5,6\}$ passes that weaker test but fails the strong one because $4\mid6^2$.
Now define
$$
F(n)=\max\{|A|:A\subseteq[1,n],\ A\text{ is strongly }2\text{-primitive}\}.
$$
This is a packing problem. The host interval is fixed, and we directly construct the largest possible forbidden-divisibility family. The all-primes set gives the leading term $\pi(n)$. In 1938 Erdős proved upper and lower bounds of the form
and later asked whether the second-order term has an asymptotic constant. This is the modern Erdős Problem #793. The supplied 2026 manuscript proposes that the constant is $27/2$; it is important not to say that Erdős himself conjectured this numerical value.
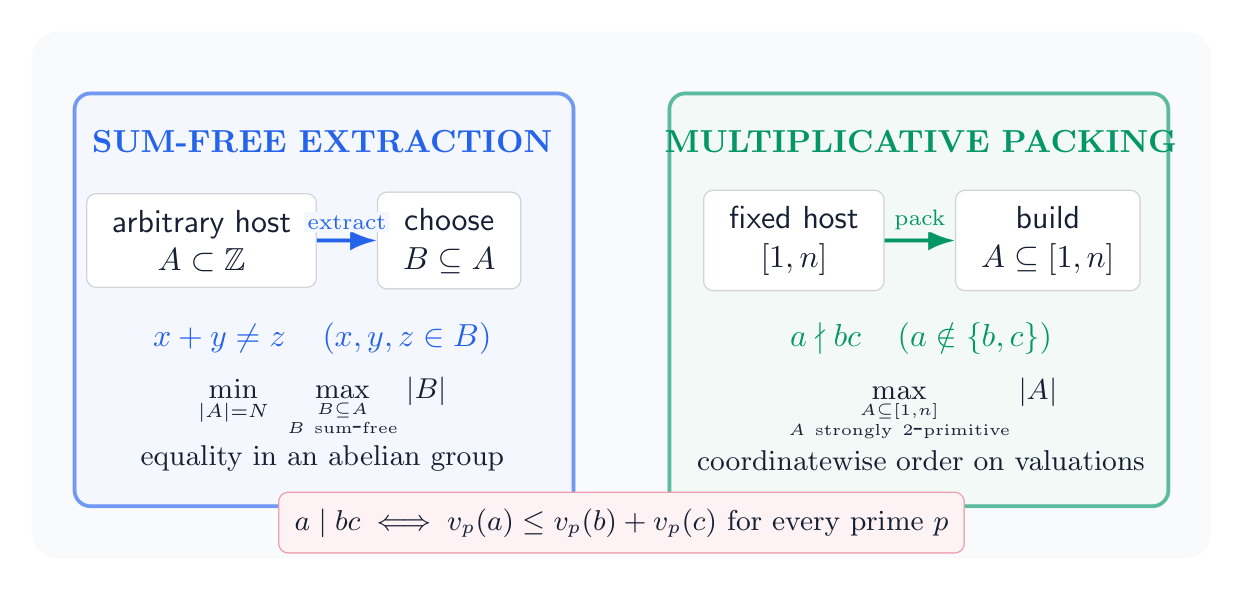
Figure 1. The quantifiers already separate the two questions. Sum-free theory extracts a subset from an arbitrary host; the multiplicative problem packs a forbidden-divisibility family into a fixed interval.
1.3 Equality versus order
The relation $a\nmid bc$ is not ordinary product-freeness. The set $\{6,10,15\}$, for instance, has no internal equality $xy=z$, yet $6\mid10\cdot15$. Prime valuations expose the real geometry:
$$
a\mid bc
\quad\Longleftrightarrow\quad
v_p(a)\le v_p(b)+v_p(c)
\quad\text{for every prime }p.
$$
Thus the forbidden relation is a coordinatewise domination inequality in the divisor lattice. For squarefree integers, if $E_a=\{p:p\mid a\}$, it becomes
$$E_a\subseteq E_b\cup E_c.$$
So the natural combinatorial object is a $2$-cover-free family, not the solution set of a linear equation. Fourier characters are superb at detecting equations such as $x+y=z$. They do not come with an evident contractive projection that detects the partial order $\nu(a)\le\nu(b)+\nu(c)$. This is the first reason Bedert’s proof cannot simply be copied into the multiplicative setting.
2. The $27/2$ upper bound: every element needs a private factor
The upper bound begins with a small lemma that contains more information than the inequality it proves.
Private-factor lemma. Let $\mathcal B$ be a set of positive integers, and choose for every $a\in A$ a factorization $a=u_av_a$ with $u_a,v_a\in\mathcal B$. If $A$ is strongly $2$-primitive, then $|A|\le|\mathcal B|$.
Think of $E_a=\{u_a,v_a\}$ as a two-element multiset. If $u_a\ne v_a$ and neither coordinate is private to $a$, another chosen pair contains $u_a$ and another contains $v_a$; the corresponding two elements have product divisible by $a$. If $u_a=v_a=x$, failure of privacy would give another pair containing $x$ twice, hence another element equal to $x^2=a$. Therefore every $a$ has a private coordinate, and these coordinates are distinct. That is the injection $A\hookrightarrow\mathcal B$.
The manuscript chooses the multiplicative $2$-basis
Every $m\le n$ can be factored into two elements of $\mathcal B=\mathcal B_0\cup\mathcal B_1\cup\mathcal B_2\cup\mathcal B_3$. The case split is elementary but carefully tuned. Small $m$ can be balanced into two factors below $n^{3/5}$, a prime factor above $n^{2/5}$ can be split off, and the remaining difficult case groups two of the three largest prime factors into an element of $\mathcal B_2$ or $\mathcal B_3$.
The main prime layer comes from $\mathcal B_1$. The genuinely second-order counts are
The private-factor injection then gives the upper bound. A caution that becomes crucial for stability: $\mathcal B_2$ and $\mathcal B_3$ are labels in an upper-bound certificate. Near-saturation of these labels does not immediately say that the original elements of $A$ are themselves products of two or three primes.
3. The lower bound: turn properly coloured edges into prime triples
The lower bound lives in a linear $3$-uniform hypergraph. Let $\mathcal H$ be a family of triples of distinct primes such that any two triples share at most one prime and every edge product is at most $n$. Define
$$
A_{\mathcal H}
=\{p\le n:p\text{ prime and }p\notin V(\mathcal H)\}
\cup
\left\{\prod_{p\in E}p:E\in\mathcal H\right\}.
$$
Why is this strongly $2$-primitive? A target triple product has three distinct prime coordinates. Each other hyperedge supplies at most one of them, so two other elements supply at most two. The same argument still works when the two witnesses coincide. Primes outside the vertex set remain singleton elements and cannot divide any other chosen element.
3.1 Logarithmic prime bins
Fix a small mesh $h\gt0$ and divide primes near $y=n^{1/3}$ into bins
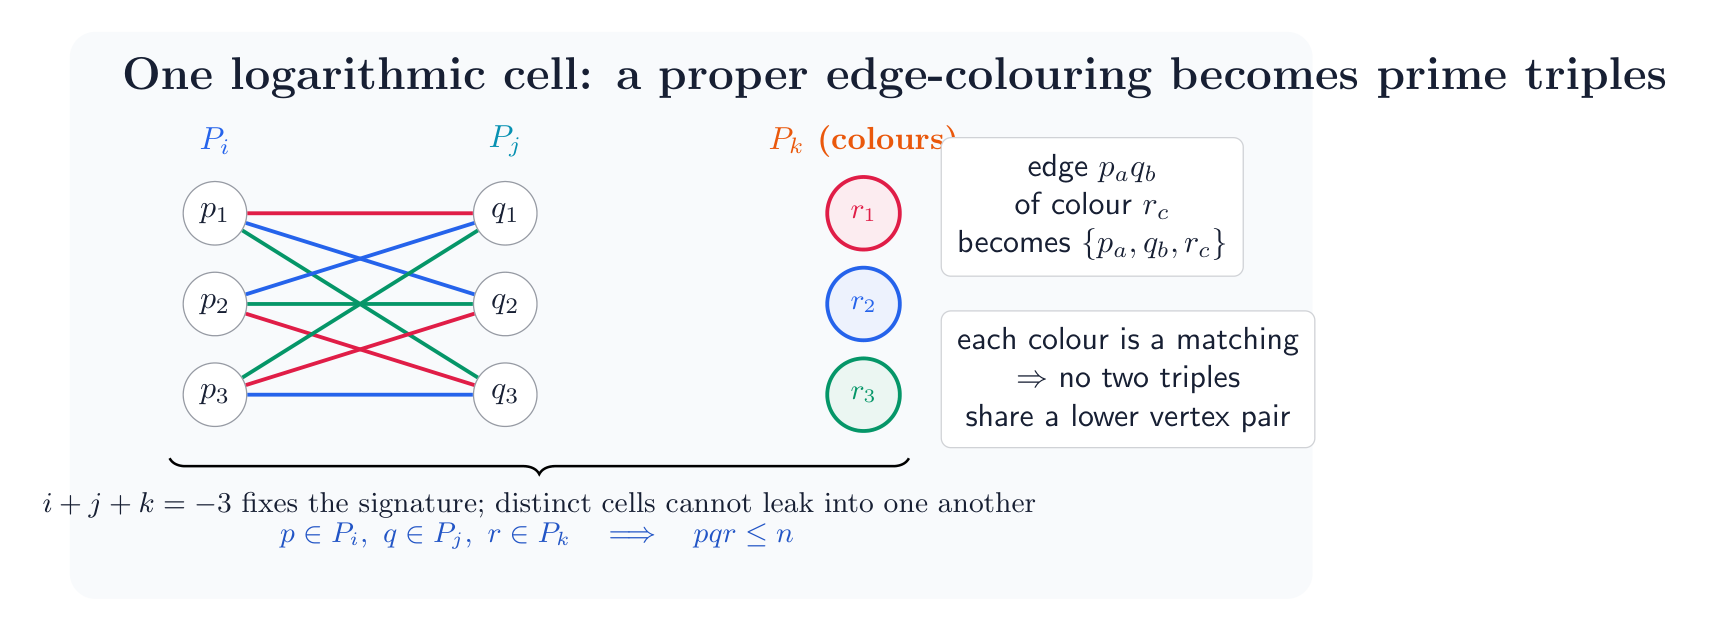
put $k=-i-j-3$. Then $i\le j\lt k$, and any $p\in P_i$, $q\in P_j$, $r\in P_k$ obeys $pqr\le n$.
If $i\lt j$, properly edge-colour the complete bipartite graph between $P_i$ and $P_j$, using primes of $P_k$ as colours. When $i=j$, do the same with the complete graph on $P_i$. The lower pair $\{p,q\}$, coloured by $r$, becomes the hyperedge $\{p,q,r\}$.
Figure 2. Within a cell, every colour class is a matching, so two produced triples never share a lower pair. Across cells, the sorted signature $(i,j,k)$ has fixed sum $-3$; two shared bin indices force the third and hence force the same cell.
The proper colouring is the local no-interference mechanism. The constant-sum signature is the global one. Together they make the union over all cells a linear hypergraph.
3.2 The cell weight
For any fixed finite collection of bins, the prime number theorem gives
$$|P_i|=(3+o(1))M\Delta_i.$$
Off the diagonal, a cell contributes approximately $9M^2\Delta_i\Delta_j$ edges. A diagonal cell contributes half as many unordered pairs. The exact geometric-series identity is
The number of vertices used is only $o(\Sigma_n)$. Replacing those primes by the triple products therefore yields the matching lower bound.
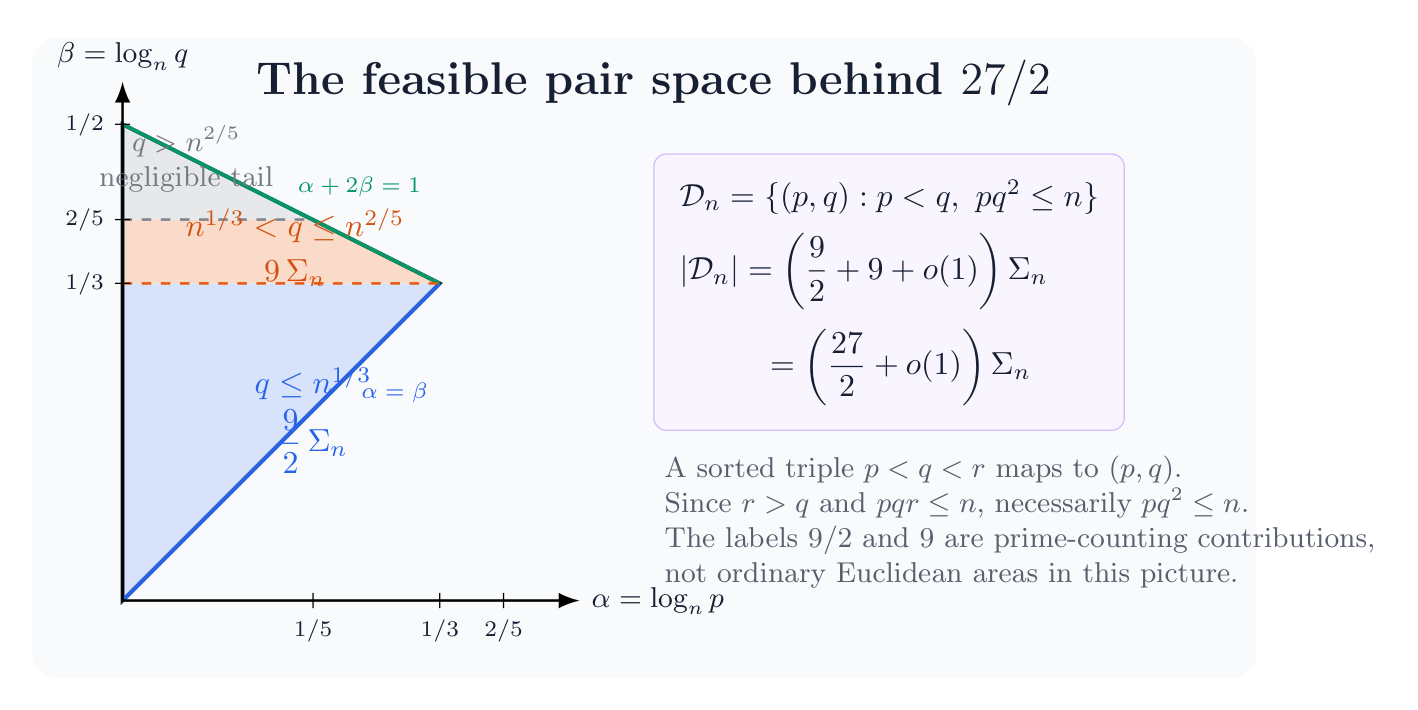
Figure 3. The same constant is visible in the canonical feasible pair space. The labels $9/2$ and $9$ are prime-counting contributions, not Euclidean areas of the drawing.
4. From Erdős’s middle third to Bedert’s $c\log\log N$
We now return to the additive problem. Let $\mathbb T=\mathbb R/\mathbb Z$, and let $\phi=\mathbf1_{(1/3,2/3)}$. The middle third of the circle is sum-free: two points in it cannot add, modulo $1$, to another point in it. Therefore, for every $x\in\mathbb T$,
$$A_x=\{a\in A:ax\pmod1\in(1/3,2/3)\}$$
is sum-free. Averaging $|A_x|$ over $x$ gives $|A|/3$. The problem is to force a positive fluctuation above that mean.
After a harmless normalization, the relevant Fourier series has the form
where $\chi$ is the non-principal real character modulo $3$. A lower bound for $\|F_A\|_1$ gives a one-sided large value and hence a large sum-free subset.
4.1 Where Bourgain’s sieve loses a logarithm
The historical correction is worth making explicit. The relevant predecessor is Jean Bourgain’s 1997 paper, not “John Bogan, 1993.” Also, the Littlewood $L^1$ conjecture had already been proved in 1981, independently by McGehee-Pigno-Smith and Konyagin. Bourgain’s argument combines Fourier analysis with a Möbius operation that filters harmonic indices.
Schematically, if $R_Q$ denotes the positive $Q$-rough integers, then
under the triangle inequality. If $Q$ is large enough to make the rough remainder negligible directly, this factor consumes the logarithm delivered by a Littlewood-type lower bound. This explains why merely “using the Littlewood theorem harder” does not produce the desired unbounded gain.
4.2 Bedert’s split: medium primes are sieved, small primes are projected
Bedert chooses
$$Q_1=(\log N)^{1/2},\qquad Q=(\log N)^{20}.$$
He Möbius-sieves only the medium primes $Q_1\le p\le Q$. Their reciprocal sum is $O(1)$, so the norm loss is a constant rather than a logarithm. The small primes $p\le Q_1$ are handled by a different operation.
For every small prime, record the exact valuation $\nu_p(a)$ and the unit residue after removing that prime power. Chinese remaindering packages all this data into a joint fibre $A(r,\nu)$. Fourier projection to a residue class,
At the main valuation level, the projection removes small-prime harmonic contamination without paying the full Möbius product. After truncation, one sees a large exponential sum plus an $L^2$-small error, to which a robust McGehee-Pigno-Smith test function applies.
At a general valuation level, lower fibres can still leak into the projected channel. Bedert proves an isolation-or-descent alternative: either the desired $L^1$ lower bound is already present, or a large fibre has a strictly lower fibre losing at most a controlled polylogarithmic factor. Iterating and reversing this descent produces a chain
Let $g_i$ be the normalized indicator of the $i$-th residue block and put $Q_i(x)=\exp(-|\widehat g_i(x)|)$. The non-Archimedean MPS test function is assembled from
The decisive observation is that $|\widehat g_i|$ is $1/q_i$-periodic, hence $\widehat Q_i$ is supported on $q_i\mathbb Z$. Multiplying an earlier block by a later $Q_k$ shifts its frequencies only by multiples of $q_k$. Since $q_i\mid q_k$, the earlier block cannot escape its residue class modulo $q_i$. Main inner products contribute one controlled unit per block, while geometric fibre growth makes the cross terms summable.
That is Bedert’s genuine no-leakage mechanism. It is more precise than the slogan “use many congruence classes and patch them.”
One further qualification prevents a common misstatement. Bedert obtains a suitable $F_4$-isomorphic model $B$ of the original set and proves the required $L^1$ bound there. The norm $\|F_A\|_1$ is not claimed to be invariant under an $F_4$-isomorphism. What is preserved is the four-term additive information needed for sum-freeness, so $S(A)=S(B)$.
Bedert’s inverse output is also stronger than the numerical lower bound. If $S(A)\le N/3+C$, his results force low additive dimension, a dense $F_4$-model, large additive energy in every substantial subset, and a “99% Structure Theorem” decomposing all but a small exceptional set into large small-doubling pieces. This is a genuine inverse theorem for host sets resisting sum-free extraction, but not an edit-distance classification by one canonical extremizer.
5. The real bridge: localize, build, prevent leakage, sum
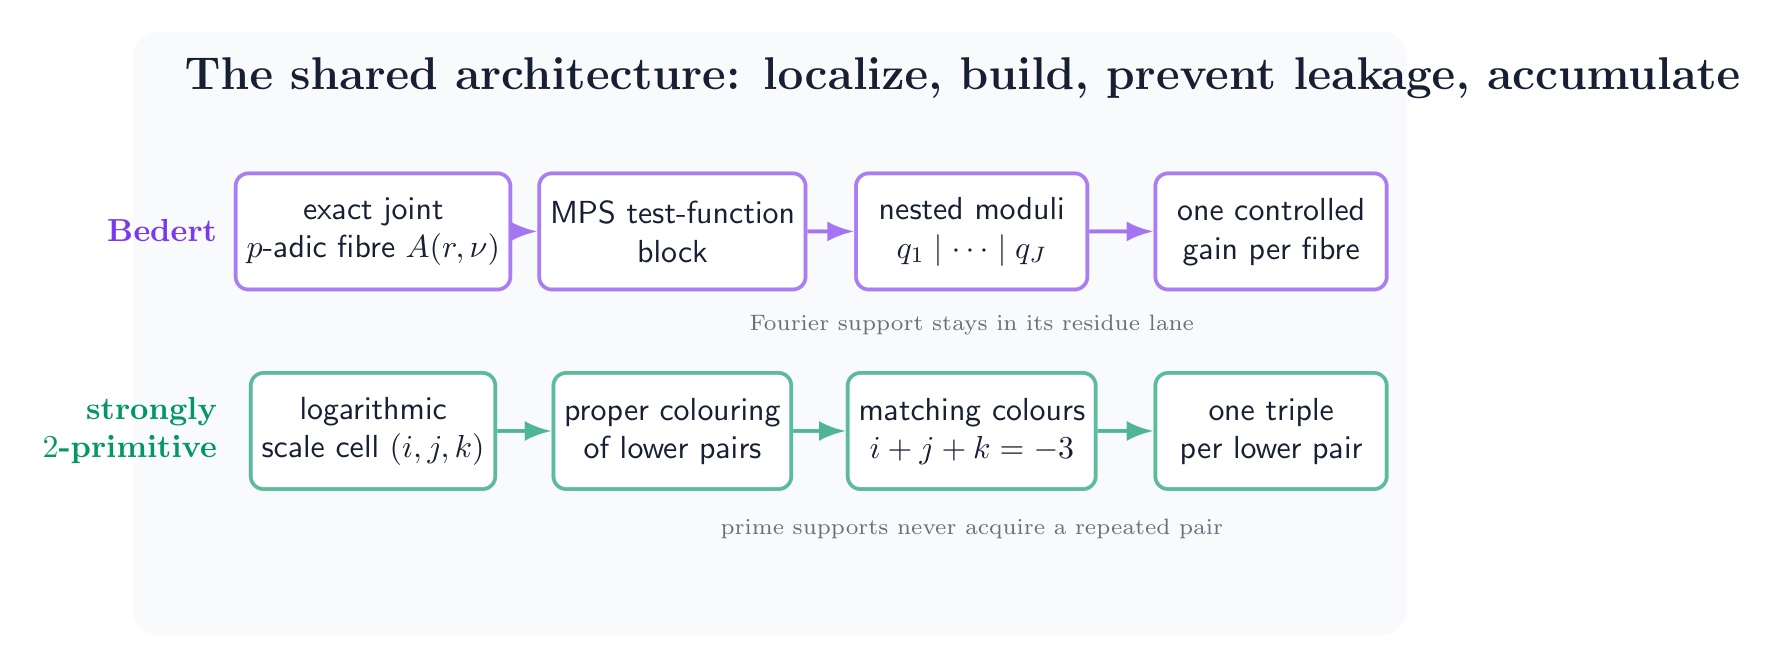
Figure 4. The analogy is architectural. Bedert preserves Fourier residue lanes through nested moduli; the multiplicative construction preserves low codegrees through matching colours and unique scale signatures.
The dictionary is now clean:
Role
Bedert’s sum-free proof
Strongly $2$-primitive proof
Underlying relation
Linear equation in an abelian group
Coordinatewise domination of prime valuations
Local coordinates
Exact small-prime valuations and unit residues
Logarithmic sizes of prime factors
Local block
Joint $p$-adic fibre and MPS block
Scale cell and properly coloured graph
No interference
Nested moduli preserve Fourier support
Colour matchings and unique cell signatures preserve linearity
Accumulation
One controlled inner product per fibre
One triple per admissible lower pair
Inverse output
Additive dimension, energy, small-doubling pieces
Private factors and a cover-free exponent core
This is a substantial connection, but it is a connection of proof design. Bedert’s Fourier projection has no direct analogue for the divisor partial order. The most plausible transfer is therefore not a line-by-line proof but a research program: find a multiplicative localization, an isolation-or-descent alternative, and a no-leakage invariant that survives repeated prime powers and larger supports.
6. The first stability guess is false
The lower construction suggests a tempting statement: every set with
should differ in only $o(\Sigma_n)$ places from almost all primes plus a near-optimal linear family of triple products. Two examples show why this is too rigid.
6.1 A private-prime lift
Start with a near-optimal linear triple family $\mathcal H_n$ using odd primes below $n/2$. Keep primes above $n/2$, replace every unused prime $p\le n/2$ by $2p$, and retain the triple products. Each $2p$ has the private prime divisor $p$; no other chosen element contains that prime. The triple products are still protected by linearity. The new set remains strongly $2$-primitive and has the same second-order asymptotic size.
But essentially every prime below $n/2$ has been replaced by a composite. The symmetric-difference distance from the all-primes model is
So literal edit-distance stability fails by much more than the scale of the second-order term.
6.2 A nonlinear sunflower at almost no cost
Even if we insist on squarefree triple products, linearity need not hold in the original representation. Add a sunflower
$$\{\{2,3,r\}:r\in R\}$$
for many private petals $r$. Remove the singleton primes $2,3,r$ and add the products $6r$. The net cardinality loss is only $2$, while the support family contains $\asymp n/\log n$ edges sharing the pair $\{2,3\}$. It is $2$-cover-free because every target has its own private petal, but any linear subfamily contains at most one sunflower edge.
The two examples have the same cause: degree-one prime coordinates carry a huge amount of neutral decoration. Stability can only become true after quotienting out this freedom.
7. Near equality in the upper bound is an exact star forest
Fix the chosen factorizations $a=u_av_a$ from the multiplicative basis proof. Make a graph $G_A$ with vertex set $\mathcal B$, one edge $\{u_a,v_a\}$ for each $a\in A$, and allow loops.
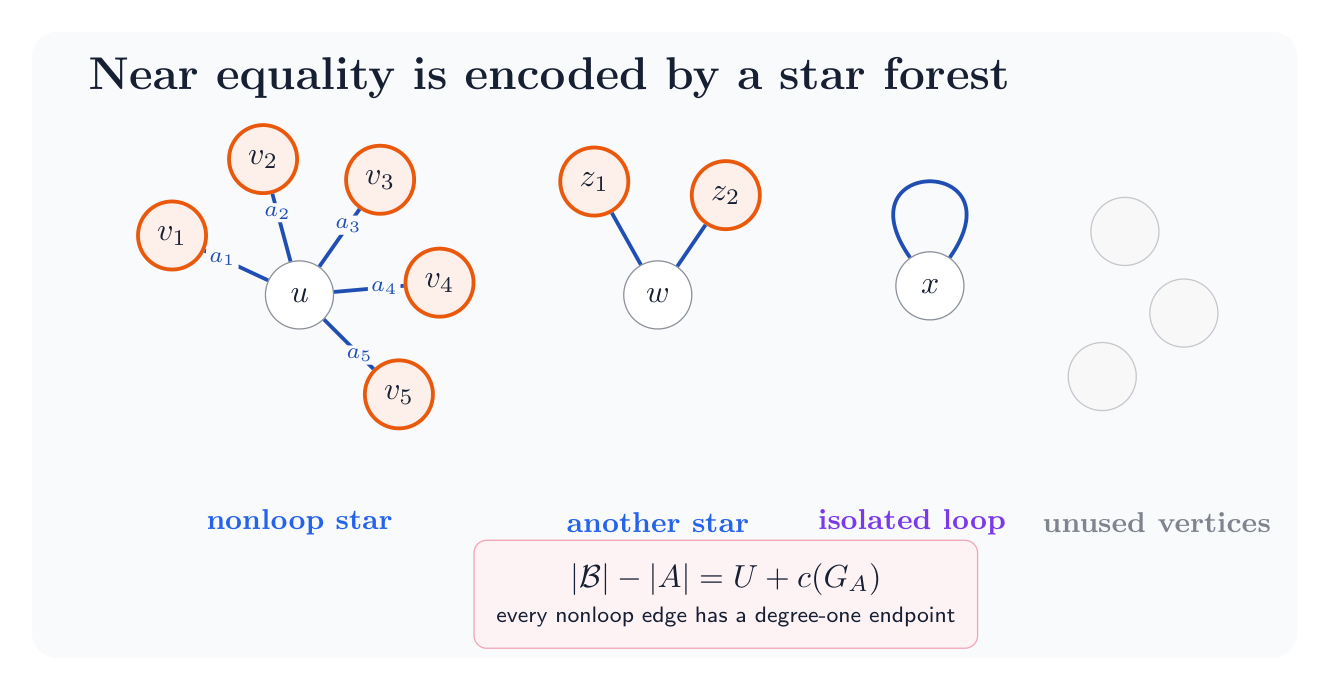
Exact factor-graph theorem. Every nonloop edge has a degree-one endpoint, and every loop is an isolated component. Thus $G_A$ is a disjoint union of stars and isolated loops. If $U$ is the number of unused vertices and $c(G_A)$ is the number of nonloop star components, then
$$|\mathcal B|-|A|=U+c(G_A).$$
The proof is the private-factor lemma read without discarding information. If a nonloop edge $\{u,v\}$ had both endpoints in other edges, the corresponding two elements would have product divisible by $uv=a$. If a loop at $u$ met another edge, then $u^2$ would divide the square of the other element.
Figure 5. The upper-bound defect is counted exactly: an unused basis coordinate costs one, and each nonloop star component costs one.
then the defect $D_n=|\mathcal B|-|A|$ is at most $(\delta_n+o(1))\Sigma_n$. Hence almost every secondary coordinate in both $\mathcal B_2$ and $\mathcal B_3$ occurs in exactly one chosen factor pair. This is a rigorous stability theorem for the upper-bound certificate. It is not yet a classification of the original integers.
8. Private-prime compression gives the correct normal form
Suppose a prime $p$ divides $a\in A$ and divides no other element of $A$. Replacing $a$ by $p$ preserves the cardinality and strong $2$-primitivity. The new target $p$ cannot divide a product of two other elements because neither contains $p$; for any unchanged target, replacing $a$ by a divisor only decreases the product available to cover it.
For primes $p\gt n^{3/5}$, the basis factorization can be chosen to expose $p$ in every multiple. Thus a degree-one large-prime coordinate is genuinely a globally private prime and can be contracted. Contract all such coordinates simultaneously.
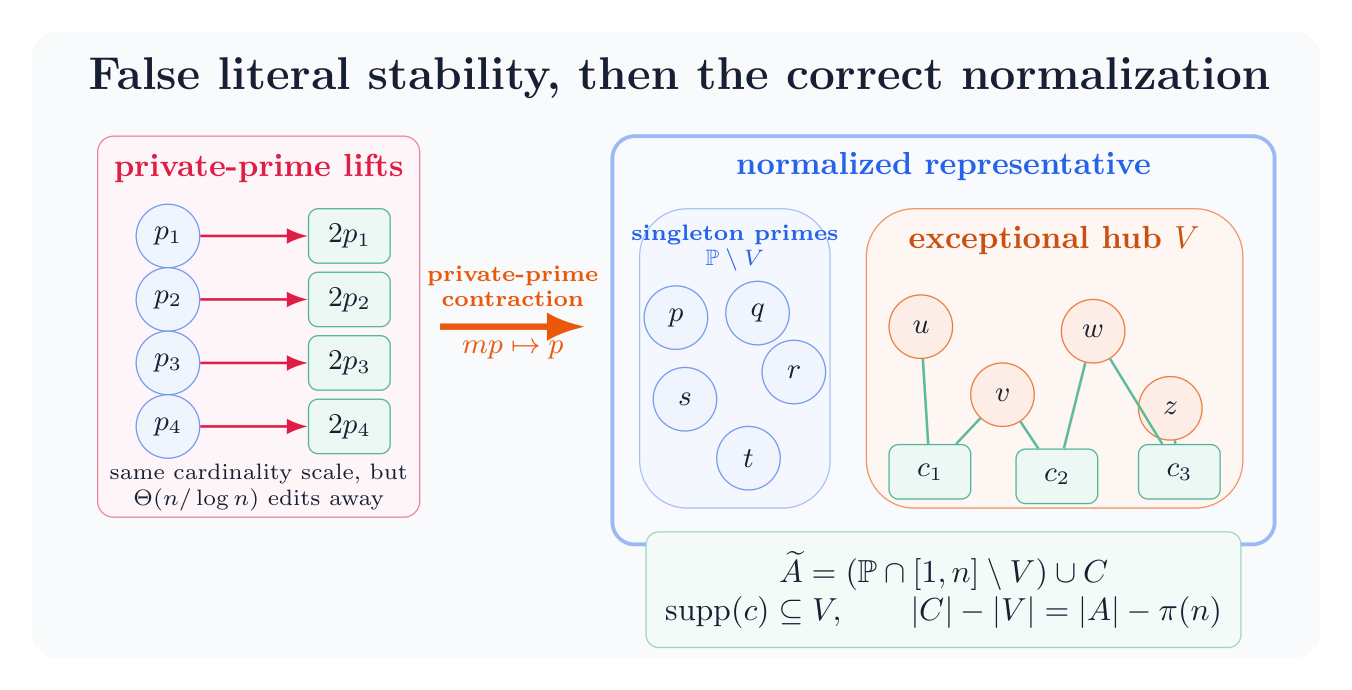
Normalized stability modulo private-prime lifts. From every strongly $2$-primitive $A\subseteq[1,n]$ satisfying the near-extremal bound above, private-prime contractions produce a strongly $2$-primitive set $\widetilde A$ of the same size with
The geometry is now transparent. Before compression, the leading $\pi(n)$ coordinates may be represented by arbitrary private multiples. After compression, almost every prime appears literally. Every residual composite is supported entirely on the small exceptional prime hub $V$, and its excess over the missing primes is exactly the second-order gain.
Figure 6. Literal stability fails on the left. The quotient by private-prime contractions produces the exact normal form on the right.
There is one more unconditional consequence. At most $|V|$ members of $C$ have support of size at most two. Indeed, any one- or two-prime residual element must have a valuation coordinate in which it is a strict global maximum; assign the element to such a prime. Two elements cannot receive the same prime. Therefore, in a normalized near-extremizer, all but $o(\Sigma_n)$ residual composites have at least three distinct prime divisors.
This is close to the hoped-for triple picture, but it does not prove that the typical element has exactly three prime factors, that it is squarefree, or that its prime factors lie near $n^{1/3}$.
9. Conditional stability when the residual core is made of triples
Now impose an additional hypothesis:
Squarefree-triple hypothesis. All but $o(\Sigma_n)$ elements of $C$ are products of three distinct primes.
Let $\mathcal H$ be the support family of those triples. Strong $2$-primitivity says precisely that it is $2$-cover-free:
$$
E\nsubseteq F\cup G
\qquad(E,F,G\in\mathcal H,\ E\notin\{F,G\}),
$$
with $F=G$ allowed.
9.1 Pruning to a linear core
If two triples $E,F$ share a pair and $x$ is the third vertex of $E$, then $x$ has degree one. Otherwise another edge $G$ containing $x$, together with $F$, would cover $E$. Delete such a petal edge whenever a repeated pair occurs. Every deletion removes at least one vertex as well as one edge, so the excess $|\mathcal H|-|V(\mathcal H)|$ does not decrease.
The result is a linear subfamily $\mathcal L$ with
and only $o(\Sigma_n)$ edges are lost in the normalized near-extremal setting. Notice the nuance: linearity is recovered after pruning private petals; it is not asserted for every cover-free representation.
9.2 Saturating the feasible pair space
Define
$$
\mathcal D_n=
\{(p,q):p\lt q\text{ prime and }pq^2\le n\}.
$$
Sort an edge of $\mathcal L$ as $p\lt q\lt r$ and map it to $(p,q)$. Linearity makes this map injective. Since $r\gt q$ and $pqr\le n$, the image lies in $\mathcal D_n$. Direct counting gives
The range $q\le n^{1/3}$ contributes $(9/2+o(1))\Sigma_n$; the range $n^{1/3}\lt q\le n^{2/5}$ contributes $(9+o(1))\Sigma_n$; the tail is negligible. Since the linear core already has $(27/2-o(1))\Sigma_n$ edges, its lower-pair map misses only $o(\Sigma_n)$ feasible pairs.
Moreover, for every fixed $\varepsilon\gt0$, all but $o(\Sigma_n)$ edges satisfy
This is the desired scale stability. It does not imply uniqueness. Different one-factorizations or different proper edge-colourings can change $\Theta(\Sigma_n)$ triples while preserving the same pair occupancy and extremal count. The stable object is the saturated pair space, not an individual colouring.
10. The remaining inverse problem is weighted and cover-free
After normalization, write every $c\in C$ as an exponent vector
and that almost every vector has support at least three. What remains unknown is the sharper assertion
$$
\#\{c\in C:c\text{ is not a squarefree product of three primes}\}
=o(\Sigma_n).
$$
This gap may conceal genuine alternative near-extremizers. If a triple $pqr$ has product slack, one can contemplate replacing it by $2pqr$ while deleting the singleton prime $2$. For a linear support family, the underlying three private coordinates still prevent coverage. It is not known whether a positive density of such bounded-hub multiplier layers can coexist globally near the $27/2$ threshold, or whether cross-layer collisions force them to be negligible.
Open normalized stability problem. Classify weighted $2$-cover-free exponent families under the product constraint $c\le n$ whose excess is $(27/2-o(1))\Sigma_n$. Decide whether the residual core is predominantly squarefree of support three, or whether bounded-hub multiplier layers produce genuinely different normalized near-extremizers.
10.1 What a Bedert-style descent would need
The additive proof suggests three design requirements, not three ready-made lemmas.
A local order projection. One needs to isolate a valuation or support layer while controlling contamination from lower exponent vectors. A divisor-lattice zeta or Möbius transform is a possible language, but no analogue of Bedert’s $L^1$-contractive residue projection is presently available.
An isolation-or-descent alternative. If the secondary basis slots do not have predominantly prime cofactors, the argument should descend to a structured hub of repeated factors with a quantitative gain or a summable loss.
A no-leakage invariant. Low codegree and scale signatures work for squarefree triples. A general invariant must survive repeated exponents and supports of size at least four.
The star-forest theorem is already a first inverse statement of this kind: near equality forces almost every basis coordinate to be a leaf attached to a small collection of hubs. The hard step is to turn that certificate-level hub structure into a classification of the original weighted exponent vectors.
11. What is proved, conditional, and open
Published/preprint additive result: Bedert proves $S(A)\ge |A|/3+c\log\log|A|$, together with inverse information involving additive dimension, dense $F_4$-models, energy and a $99\%$ decomposition into large small-doubling pieces.
Supplied 2026 manuscript: the claimed $27/2$ asymptotic follows from the multiplicative-basis upper bound and the logarithmic-cell hypergraph construction described above. The status caveat at the beginning remains in force.
Unconditional stability developed in the accompanying note: literal edit stability is false; the upper-bound factor graph is an exact star forest; private-prime compression gives the normal form $(\mathbb P\setminus V)\cup C$; and almost every residual composite has at least three distinct prime divisors.
Conditional stability: if almost all residual composites are squarefree triples, pruning gives a near-maximal linear core whose lower pairs saturate $\mathcal D_n$, and almost every prime factor lies at scale $n^{1/3+o(1)}$.
Open: prove that the normalized residual core is predominantly squarefree of support three, or construct a different near-extremal weighted cover-free core.
The conceptual moral is simple but useful. Bedert’s $p$-adic fibres and the multiplicative logarithmic cells are not the same mathematical object. Yet both proofs win by choosing coordinates in which local constructions can be made strong and then finding an exact invariant that prevents those constructions from interfering. In the stability problem, the same philosophy says to quotient the neutral directions first. Once private-prime lifts are removed, the true obstruction becomes visible: a weighted cover-free family on a tiny prime hub. That is the right object for the next theorem.
P. Chojecki, The Second Term for Strongly 2-Primitive Sets, user-supplied five-page manuscript, July 2026; no public identifier located at the time of writing.
We begin with the Weierstrass form of elliptic equation, i.e. look it as an embedding cubic curve in .
Definition 1 (Weierstrass form), In general the form is given by,
If , then, we have a much more simper form,
Remark 1
Where .
We have two way to classify the elliptic curve living in a fix field . \paragraph{j-invariant} The first one is by the isomorphism in . i.e. we say two elliptic curves is equivalent iff
is a isomorphism such that .
Definition 2 (j-invariant) For a elliptic curve , we have a j-invariant of , given by,
Why j-invariant is important, because j-invariant is the invariant depend the equivalent class of under the classify of isomorphism induce by . But in one equivalent class, there also exist a structure, called twist.
Definition 3 (Twist) For a elliptic curve , all elliptic curve twist with is given by,
So the twist of a given elliptic curve is given by:
Remark 2 Of course a elliptic curve is the same as , induce by the map .
But this moduli space induce by the isomorphism of is not good, morally speaking is because of the abandon of universal property. see \cite{zhang}. \paragraph{Level structure} We need a extension of the elliptic curve , this is given by the integral model.
Definition 4 (Integral model), . is regular and minimal, the construction of is by the following way, we first construct and then blow up. is given by the Weierstrass equation with coefficent in .
Remark 3 The existence of integral model need Zorn’s lemma.
Definition 5 (Semistable) the singularity of the minimal model of are ordinary double point.
Remark 4 Semistable is a crucial property, related to Szpiro’s conjecture.
Definition 6 (Level structure)
The weil pairing of is given by a unit in cycomotic fields, i.e.
What happen if ? In this case we have a analytic isomorphism:
Given by,
Where , and the Weierstrass equation is given by . The full n tructure of it is given by and the value of , i.e.
Where is induce by
The key point is following:
Theorem 7, the moduli of elliptic curves with full level n-structure is identified with
Now we discuss the Mordell-Weil theorem.
Theorem 8 (Mordell-Weil theorem)
The proof of the theorem divide into two part:
Weak Mordell-Weil theorem, i.e. , is finite.
There is a quadratic function,
, is finite.
Remark 5 The proof is following the ideal of infinity descent first found by Fermat. The height is called Faltings height, introduce by Falting. On the other hand, I point out, for elliptic curve , there is a naive height come from the coefficient of Weierstrass representation, i.e. .
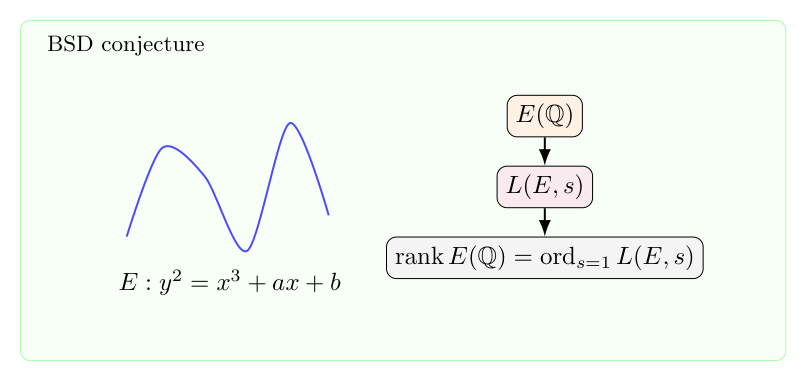
While the torsion part have a very clear understanding, thanks to the work of Mazur. The rank part of is still very unclear, we have the BSD conjecture, which is far from a fully understanding until now.
But to understanding the meaning of the conjecture, we need first constructing the zeta function of elliptic curve, .
\paragraph{Local points} We consider a local field , and a locally value map , then we have the short exact sequences,
Topologically, we know are union of disc indexed by ,
. Define , then we have Hasse principle:
Theorem 9 (Hasse principle)
Remark 6 I need to point out, the Hasse principle, in my opinion, is just a uncertain principle type of result, there should be a partial differential equation underlying mystery.
So count the points in reduce to count points in , reduce to count the Selmer group . We have a short exact sequences to explain the issue.
I mention the Goldfold-Szipiro conjecture here. , there such that:
\paragraph{L-series} Now I focus on the construction of , there are two different way to construct the L-series, one approach is the Euler product.
Where or when has bad reduction on .
The second approach is the Galois presentation, one of the advantage is avoid the integral model. Given is a fixed prime, we can consider the Tate module:
Then by the transform of different embedding of , we know , decompose it into a lots of orbits, so we can define , the decomposition group of (extension of to ). We define is the inertia group of .
Then is generated by some Frobenius elements
So we can define
And then .
Faltings have proved is the invariant depending the isogenous class in the follwing meaning:
Theorem 10 (Faltings) is an isogenous ivariant, i.e. isogenous to iff , .
Where come from an automorphic representation for . Now we give the statement of BSD onjecture. is the regulator of , i.e. the volume of fine part of with respect to the Neron-Tate height pairing. be the volume of Then we have,
.
.
Here is an explictly positive integer depending only on for dividing .
补充说明
以下是新整理的中文说明;上方旧博客原文保持不变。
Birch and Swinnerton-Dyer 猜想把椭圆曲线的有理点群和它的 $L$ 函数在 $s=1$ 处的零点阶联系起来。它是数论中最核心的桥之一:一边是 Diophantine 方程的解,另一边是解析函数的特殊值。
Remark 1 Why it is but not 1? if it is 1, then the action distribute is not trasitive on , i.e. every element in unite group present a connected component
Now we consider the subgroup .
We are most interested in the case . So how to investigate ? We can look at the action of it on something, for particular, we look at the action of it on Riemann sphere, i.e. given by fraction linear map:
Remark 2 What is fraction linear map? This action carry much more information than the action on vector, thanks for the exist of multiplication in and the algebraic primitive theorem. Due to I always looks the fraction linear map as something induce by the permutation of the roots of polynomial of degree 2, this is true at least for fix points, and could natural extension. So how about the higher dimension generate? consider the transform of tuples induce by polynomial with degree ?
Remark 3
, then action faithful on , i.e. except identity, every action is nontrivial. This is easy to be proved, observed,
Up half plane is invariant under the action of , i.e. , . The proof is following,
Now we focus on or the same,. All the argument for make sense for
Fix , define,
Then is the kernel of map , i.e. we have short exact sequences,
Remark 4 The relationship of is just like .
Definition 1 (Congruence group) A subgroup of is called a congruence group iff , .
Example 1 We give two examples of congruence subgroups here.
Definition 2 (Fundamental domain)
Now here is a theorem charistization the fundamental domain.
Theorem 3 This domain is a fundamental domain of
Proof: Ths key point is have two generators,
.
.
Thanks to this two generator exactly divide the action of on into a lots of scales, then is a fundamental domain is a easy corollary.
Remark 5 This is not rigorous, need be replace by , but this is very natural to get a modification to a right one.
Remark 6 are equivalent iff and or if on the unit circle and
Remark 7 If , then expect in the following three case:
if .
if .
if .
Where .
Remark 8 The group is generated by the two elements , . In other word, any fraction linear transform is a “word” induce by . But not free group, we have relationship .
The natural function space on is the memorphic function, under the map: , it has a -expension,
And there are only finite many negative such that .
Remark 1 I thought this problem initial 5 years ago, cost me several days to find a answer, I definitely get something without the argument of Dirchlet hyperbola method and which is weaker but morally the same camparable with the result get by Dirichlet hyperbola method.
Remark 2 How to get the formula:
In fact,
Which is the integer lattices under or lying on the hyperbola .
Remark 3 By trivial argument, we can bound the quantity as following way,
The error term is , which is too big. But fortunately we can use the symmetry of hyperbola to improve the error term.
Proof:
Theorem 2
Given a natural number k, use the hyperbola method together
with induction and partial summation to show that
where denotes a polynomial of degree with leading term .
Remark 4 is the residue of at .
Proof:
We can establish the dimension 3 case directly, which is the following asymptotic formula,
The approach is following, we first observe that
The problem transform to get a asymptotic formula for the lattices under 3 dimension hyperbola. The first key point is, morally is the central point under the hyperbola.
Then we can divide the range into 3 parts, and try to get a asymptotic formula for each part then add them together. Assume we have:
.
.
.
Then the task transform to get a asymptotic formula,
But we can do the same thing for and then integral it. This end the proof. For general , the story is the same, by induction.
Induction on and use the Fubini theorem to calculate .
There is a major unsolved problem called Dirichlet divisor problem.
What is the error term? The conjecture is the error term is , it is known that is not right.
Remark 5
To beats this problem, need some tools in algebraic geometry.
2. Several problems
, is there a asymptotic formula for ?
, is a polynomial with degree , is there a asymptotic formula for ?
, is a polynomial with degree , is there a asymptotic formula for ?
Remark 6 In fact we can get , by combining the theorem 3 and 1.
3. Lattice points in ball
Gauss use the cube packing circle get a rough estimate,
In the same way one can obtain,
Remark 7 Where is the volume of the unit ball in dimension.
Dirchlet’s hyperbola method works nicely for the lattic points in a ball of dimension . Langrange proved that every natural number can be represented as the sum of four squares, i.e. , and Jacobi established the exact formula for the number of representations
Hence we derive,
This result extend easily for any , write as the additive convolution of and , i.e.
Apply the above result for and execute the summation over the remaining squares by integration.
Remark 8 Notice that this improve the formula 12 which was obtained by the method of packing with a unit square. The exponent in 16 is the best possible because the individual terms of summation can be as large as the error term (apart from ), indeed for we have if is odd by the Jacobi formula. The only case of the lattice point problem for a ball which is not yet solved (i.e. the best possible error terms are not yet established) are for the circle() and the sphere ().
Theorem 4
4. Application in finite fields
Suppose is a irreducible polynomial. And for each prime , let
By Langrange theorem we know . Is there a asymptotic formula for
A general version, we can naturally generated it to algebraic variety.
Is there a asymptotic formula for
Example 1 We give an example to observe what is involved. . We know is solvable iff or . One side is easy, just by Fermat little theorem, the other hand need Fermat descent procedure, which of course could be done by Willson theorem. In this case,
Which is a special case of Dirichlet prime theorem.
Let be an algebraic number field, i.e. the finite field extension of rational numbers, let
Dedekind proved that,
Theorem 5
is a ring, we call it the ring of integer of .
He showed further every non-zero ideal of could write as the product of prime ideal in uniquely.
the index of every non-zero ideal in is finite, i.e. , and we can define the norm induce by index.
Then the norm is a multiplication function in the space of ideal, i.e. .
Now he construct the Dedekind Riemann zeta function,
Now we consider the analog of the prime number theorem. Let , does the exist a asymptotic formula,
Given a prime , we may consider the prime ideal
Where is different prime ideal in . But the question is how to find these ? For the question, there is a satisfied answer.
Lemma 6 (existence of primitive element) There always exist a primetive elements in , such that,
Where is some algebraic number, which’s minor polynomial .
Theorem 7 (Dedekind recipe) Take the polynomial , factorize it in the polynomial ring ,
Consider . Then apart from finite many primes, we have,
Where .
Remark 9 The apart primes are those divide the discriminant.
Now we can argue that 4 is morally the same as counting the ideals whose norm is divide by in a certain algebraic number theory.
And we have following, which is just the version in algebraic number fields of 2.
Theorem 8 (Weber) of ideals of with norm equal to,
I explain some general ideal in the theory of diophantine approximation, some of them is original by myself, begin with a toy model, then consider the application on folklore Swirsing-Schmidt conjecture.
\tableofcontents
1. Dirichlet theorem, the toy model
The very basic theorem in the theory of Diophantine approximation is the well known Dirichlet approximation theorem, the statement is following.
Theorem 1 (Dirichlet theorem) for all is a irrational number, we have infinity rational number such that:
Remark 1 It is easy to see the condition of irrational is crucial. There is a best constant version of it, said, instead of , the best constant in the suitable sense for the theorem 1 should be and arrive by at least. The strategy of the proof of the best constant version involve the Frey sequences.
Now we begin to explain the strategies to attack the problem.
\paragraph{Argument 1, boxes principle} We begin with a easiest one, i.e. by the argument of box principle, the box principle is following,
Theorem 2 (Boxes principle) Given and two finite sets , set , if we have a map:
Then there exists a element such that there exist at least two element , .
Proof: The proof is trivial.
Now consider, , the sequences , then . Divide in an average way to part: . Then the linear structure involve (which, in fact play a crucial role in the approach). And the key point is to look at and integers.
\paragraph{Argument 2, continue fractional} We know, for irrational number , have a infinite long continue fractional:
Then
And we have,
Then .
\paragraph{Argument 3, Bohr set argument} We begin with some kind of Bohr set:
The key point is the shift of Bohr set, on the vertical line i.e. is very slow, and can be explained by
So:
in But in fact they are not really independent, as the number of Bohr sets increase, then you can calculate the correlation, thanks to the harmonic sires increasing very slowly, wwe can get something non trivial by this argument, but it seems not enough to cover the whole theorem 1.
\paragraph{Argument 4, mountain bootstrap argument} This argument is more clever than 3, although both two arguments try to gain the property we want in 1 from investigate the whole space but not , this argument is more clever.
Now I explain the main argument, it is nothing but sphere packing, with the set of balls
and define its subset
Then , and . If we can proof,
Lemma 3 For all , there is a subset of such that .
Remark 2 If we can proof 3, it is easy to see the theorem 1 follows.
Proof: The proof follows very standard in analysis, may be complex analysis? Key point is we start with a ball , whatever it is, this is not important, the important thing is we can take some ball with the center of in , then try to consider to extension and then we find the boudary is also larger then we can extension again, step by step just like mountain bootstrap argument. So we involve in two possible ending,
The extension process could extension to whole space.
we can not use the extension argument to extension to the whole space.
If we are in the first situation, then we are safe, there is nothing need proof. If we are in second case, anyway we take a ball . Then try to find good ball to approximate , but this is difficult…
Remark 3 Argument 1 is too clever to be true in generalization, argument 2 is standard, by the power of renormalization. argument 3 and argument 4 have gap… I remember I have got a proof similar to argument 4 here many years ago, but I forgot how to get it…
2. Schimidt conjecture
The Schimidt conjecture could be look as the generalization of Dirchlet approximation theorem 1 to algebraic number version, to do this, we need define the height of a algebraic number.
Definition 4 We say a number is a order algebraic number if and only is the minimal polynomial of , have degree .
Definition 5 (Height) Now we define the height of a th order algebraic number as , Where
Now we state the conjecture:
Theorem 6 (Swiring-Schimidt conjecture) For all transendental number , there is infinitely are th algebraic number such that:
Where is a constant only related to but not .
I point out the conjecture is very related to the map:
Where is the th symmetric sum.
Remark 4 is a map , what we consider is its inverse, , but is not smooth, it occur singularity when for some . And the map, as we know, the singularity depend on the quantity .
Remark 5 I then say something about the geometric behaviour of the map , as we know, what we have in mind is consider the map as a distortion , Then is just the pullback of the canonical metric on (morally) to .
高维 Diophantine approximation 会把一个数的逼近问题变成向量、线性形式或流形上的逼近问题。此时抽屉原理仍然给出基准结果,但最佳常数、例外集维数和代数数逼近会变得更深。许多问题最后会进入 geometry of numbers、dynamical systems on homogeneous spaces 或 Schmidt game 的语言。
First of all, we give the definition of discrete harmonic function.
Definition 1 (Discrete harmonic function) We say a function is a discrete harmonic function on if and only if for any , we have:
In dimension 2, the definition reduce to:
Definition 2 (Discrete harmonic function in ) We say a function is a discrete harmonic function on if and only if for any , we have:
The result establish in \cite{paper} is following:
Theorem 3 (Liouville theorem for discrete harmonic functions in ) Given . There exists a constant related to such that, given a discrete harmonic function in satisfied for any ball with radius , there is portion of points satisfied . then is a constant function in .
Remark 1 This type of result contradict to the intuition, at least there is no such result in . For example. the existence of poisson kernel and the example given in \cite{paper} explain the issue.
Remark 2 There are reasons to explain why there could not have a result in but in ,
The first reason is due to every radius there is only lattices in in so the mass could not concentrate very much in this setting.
The second one is due to there do not have infinite scale in but in .
The third one is the function in is automatically locally integrable.
The generation is following:
Theorem 4 (Liouville theorem for discrete harmonic functions in ) Given . There exists a constant related to such that, given a discrete harmonic function in satisfied for any ball with radius , there is portion of points satisfied . then is a constant function in .
In this note, I give a proof of 4, and explicit calculate a constant satisfied the condition in 3, this way could also calculate a constant satisfied 4. and point the constant calculate in this way is not optimal both in high dimension and 2 dimension.
2. some element properties with discrete harmonic function
We warm up with some naive property with discrete harmonic function. The behaviour of bad points could be controlled, just by isoperimetric inequality and maximum principle we have following result.
Definition 5 (Bad points) We divide points of into good part and bad part, good part is combine by all point such that , and is the residue one. So .
For all , we define for convenient.
Theorem 6 (The distribution of bad points) For all bad points in , they will divide into several connected part, i.e.
and every part satisfied .
Remark 3 We say is connected in iff there is a path in connected .
Remark 4 the meaning that every point So the behaviour of bad points are just like a tree structure given in the gragh.
Proof: A very naive observation is that for all is a connected compact domain, then there is a function
such that . And we have:
This could be proved by induction on the diameter if . Then, if there is a connected component of such that contradict to theorem 6 for simplify assume the connected component is just , then use the formula 5we know
The last line is due to consider around . But this lead to: which is contradict to the definition of . So we get the proof.
Now we begin another observation, that is the freedom of extension of discrete harmonic function in is limited.
Theorem 7 we can say something about the structure of harmonic function space of , the cube, you will see, if add one value, then you get every value, i.e. we know the generation space of
Proof: For two dimension case, the proof is directly induce by the graph. The case of dimensional is similar.
Remark 5 The generation space is well controlled. In fact is just like n orthogonal direction line in n dimensional case.
3. sktech of the proof for \ref
}
The proof is following, by looking at the following two different lemmas establish by two different ways, and get a contradiction.
\paragraph{First lemma}
Lemma 8 (Discrete poisson kernel) the poisson kernel in . We point out there is a discrete poisson kernel in , this is given by:
And the following properties is true:
, .
Remark 6 The proof could establish by central limit theorem, brown motion, see the material in the book of Stein \cite{stein}. The key point why this lemma 8 will be useful for the proof is due to this identity always true , So we will gain a lots of identity, These identity carry information which is contract by another argument.
\paragraph{Second lemma} The exponent decrease of mass.
Lemma 9 The mass decrease at least for exponent rate.
Remark 7 the proof reduce to a random walk result and a careful look at level set, reduce to the worst case by brunn-minkowski inequality or isoperimetry inequality.
\paragraph{Final argument} By looking at lemma 1 and lemma 2, we will get a contradiction by following way, first the value of on increasing too fast, exponent increasing by lemma2, but on the other hand, it lie in the integral expresion involve with poisson kernel, but the pertubation of poisson kernel is slow, polynomial rate in fact…
\newpage
{99} \bibitem{paper} A DISCRETE HARMONIC FUNCTION BOUNDED ON A LARGE PORTION OF Z2 IS CONSTANT
This is a note concentrate on the log average Sarnak conjecture, after the work of Matomaki and Raziwill on the estimate of multiplication function of short interval. Given a overview of the presented tools and method dealing with this conjectue.
1. Introduction
Sarnak conjecture \cite{Sarnak} assert that for any obersevable come from a determination systems , where , . The correlation of it and the Liuvillou function is 0, i.e. they are orthongonal to each other, more preseicesly it is just to say,
This is a very natural raised conjecture, Liuville function is the presentation of primes, due to we always believe the distribution of primes in should be randomness.
It has been known as observed by Landau \cite{Laudau} that the simplest case,
already equivalent to the prime number theorem. It is not difficult to deduce the spetial case of Sarnak conjecture when with the obersevation in $latex {(1)}&fg=000000$ come from finite dynamic system is equivalent to the prime number theorem in athremetic progress by the similar argument. Besides this two classical result, may be the first new result was established by Davenport,
Theorem 1 Let , is a inrational, then the obersevation come from is orthogonal to Mobius function. due to is a basis of , suffice to proof,
There is a lots of spetial situations of Sarnak’s conjecture have been established, The parts I mainly cared is the following:
Interval exchange map.
Skew product flow.
Obersevable come from One dimensional zero entropy flow.
Nilsequences.
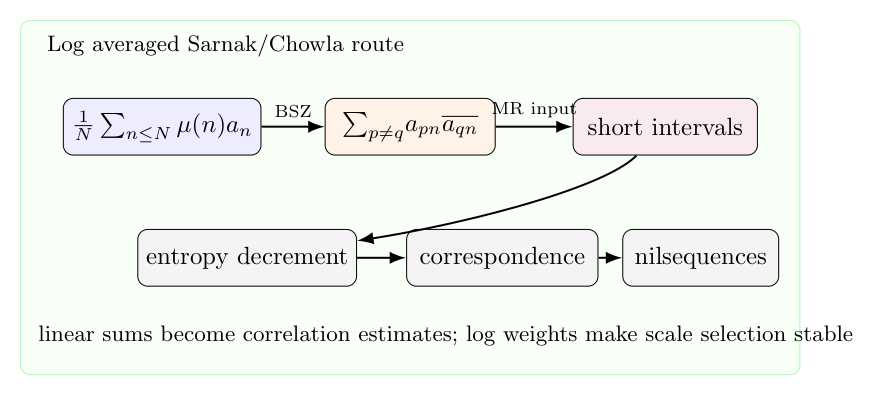
But in this note, I do not want to explain the tecnical and tools to establish this result, but considering an equivalent conjecture of Sarnak conjecture, named Chowla conjecture, and explain the underlying insight of the suitable weak statement, i.e. the log average Chowla conjecture and the underlying insight of it.
The note is organized as following way, in the next section $latex {(2)}&fg=000000$, we give a self-contained introduction on the tools called Bourgain-Sarnak-Ziegler critation, explain the relationship of this critation and the sum-product phenomenon, also given some more general critation along the philosephy use in establish the Bourgain-Sarnak-Ziegler critation, which maybe useful in following development combine with some other tools. The key point is transform the sum from linear sum to bilinear sum and decomposition the bilinear sum into diagonal part and off-diagonal part, use the assume in the critation to argue the off-diagonal part is small and on the orther hand the diagonal part is also small by the trivial estimate and the volume of diogonal is small, this is very similar to a suitable Caderon-Zugmund decomposition.
In section $latex {(4)}&fg=000000$, I try to give a proof sketch of the result of Matomaki and Raziwill, which is also a key tools to understanding the Sarnak conjecture, or equivalent the Chowla conjecture. The key points of the proof contains following:
Find a suitable fourier indentity
Construct a multiplication-addition dense subset , and proof that the theorem MR hold we need only to proof it hold for instead of
Involve the power of euler product formula. divide the whole interval into a lot of small interval with smaller and smaller scale and a residue part. We look the part come from every small scale as a major term and look the residue part as minor term.
Deal with the major term at every scale, by a combitorios identity and second moments method.
find a enough decay estimate from a scale to the next smaller scale.
Deal with the minor term by the H… lemma.
Due to the theorem of MR do not exausted the method they developed, we trying to make some more result with their method, Tao and Matomaki attain the average version of Chowla conjecture is true by this way, and combine this argument and the entropy decresment argument they established the 2 partten of the log average Chowla conjecture is true. Very recently Tao and his coperator proved the odd partten case of log average chowla conjecture is true, combine an argument of frustenberg crresponding principle and entopy decresment argument. But it seems the even and large than 2 case is much difficult and seems need something new to combine with the method of MR and entropy decresment and frunstenberg corresponfing principle to make some progress.
So, in section $latex {(5)}&fg=000000$, we give a self-contain introduction to the entropy decresment argument of Tao, and combine with the frustenberg corresponding principle.
In the last section $latex {(6)}&fg=000000$, I state some result and method and phylosphy of them I get on nilsequences and wish to combine them with the previous method to make some progress on log average Chowla conjecture on the even partten case.
\newpage
2. Bourgain-Sarnak-Zieglar creation
We begin with the easiest one, this is the main result established in \cite{BSZ}, I try to give the main ideal under the proof, but with a no quantitative version is the following,
Theorem 2 (Bourgain-Sarnak-Zieglar creation, not quantitative version) if for all primes we have:
Then for multiplication function we have
Remark 1 For simplify we identify .
Remark 2
The idea is following, break the sum into a bilinear one, so, of course, we multiplication it with itself. i.e. we consider to control,
To control 4, we need exhausted the mutiplication property of , we have . We can not get good estimate for all term,
The condition in our hand if following,
So, just like the situation of Cotlar-Stein lemma \cite{Cotlar-Stein lemma}, we wish to estimate like following:
Then we consider divide the sum into diagonal part and non-diagonal part, as following,
But the first part is small, i.e.
Because of
and the second part is small, i.e.
Because diagonal part is small in and trivial inequality
But the method in remark 2 is not always make sense in any situation, we need to construct two suitable sets and then break up into , this mean,
But this could be construct in this situation, thanks to the prime number theorem,
Theorem 3 (Prime number theorem)
Morally speaking, this is the statement that the primes, which is the generator of multiplication function, is not very sparse.
3. Van der curpurt trick
There is the statement of Van der carport theorem:
Theorem 4 (Van der curpurt trick) Given a sequences in , if , is uniformly distributed, then is uniformly distributed.
I do not know how to establish this theorem with no extra condition, but this result is true at least for polynomial flow. \newpage Proof:
This type of trick could also establish the following result, which could be understand as a discretization of the Vinegradov lemma.
Remark 3
Uniformly distribution result of : Given , coverages to a uniformly distribution in as .
Remark 4 But I definitely do not know how to establish the similar result when .
Remark 5
This trick could also help to establish estimate of correlation of low complexity sequences and multiplicative function, such as result:
Maybe with the help of B-Z-S theorem.
\newpage
4. Matomaki and Raziwill’s work
In this section we explain the main idea underlying the paper \cite{KAISA MATOMA 虉KI AND MAKSYM RADZIWILL}. But play with a toy model, i.e. the corresponding corollary of the original result on Liouville鈥檚 function.
The most important beakgrouth of analytic number theory is the new understanding of multiplication function on share interval, this result is established by Kaisa Matom盲ki and Maksym Radziwill. Two very young and intelligent superstars.
The main theorem in them article is :
Theorem 6 (Matomaki,Radziwill) As soon as when , one has:
for almost all .
In my understanding of the result, the main strategy is:
Parseval indetity, transform to Dirchelet polynomial.
Involved by multiplication property, spectral decomposition.
From linear to multilinear , Cauchy schwarz inequality.
major term estimate.
Estimate the contribution of area which is not filled.
4.1. Parseval indetity, transform to Dirchelet polynomial
We wish to establish the equality,
This is the norm, by Chebyschev inequality, this could be control by norm, so we only need to establish the following,
We wish to transform from the discretization sum to a continue sum, that is,
Remark 7 There are two points to understand why 19 and 18 are the same.
Now we try to transform 19 by Parseval indetity, this is something about the norms of the quality we wish to charge. It is just trying to understanding 19 as a quantity in physical space by a more chargeable quality in frequency space. Image,
Then . Note that,
So by Parseval identity, we have,
Remark 8 We know the Fejer kernel satisfied,
So morally speaking, we get the following identity.
In fact we do a cutoff, the quality we really consider is just:
established the monotonically inequality:
Theorem 7 (Paserval type identity)
Remark 9
In my understanding, This is a perspective of the quality, due to the quality is a multiplicative function integral on a domain with additive structure, it could be looked as a lots of wave with the periodic given by primes, so we could do a orthogonal decomposition in the fractional space, try to prove the cutoff is a error term and we get such a monotonically inequality.
But at once we get the monotonically inequality, we could look it as a聽compactification process and this process still carry most of the information so lead to the inequality.
It seems something similar occur in the attack of the moments estimate of zeta function by the second author. And it is also could be looked as something similar to the 聽spectral decomposition with some basis come from multiplication generators, i.e. primes.
4.2. Involved by multiplication property, spectral decomposition
I called it is “spectral decomposition”, but this is not very exact. Anyway, the thing I want to say is that for multiplication function , we have Euler-product formula:
But anyway, we do not use the whole power of multiplication just use it on primes, i.e. leads to following result:
This is a identity about the function , the point is it is not just use the multiplication at a point,i.e. , but take average at a area which is natural generated and compatible with multiplication, this identity carry a lot of information of the multiplicative property. Which is crucial to get a good estimate for the quality we consider about.
4.3. From linear to multilinear , Cauchy schwarz
Now, we do not use one sets , but use several sets which is carefully chosen. And we do not consider [X,2X] with linear structure anymore , instead reconsider the decomposition:
On every it equipped with a bilinear structure. And is a very small set, which is in fact have much better estimate.
Now we just use a Cauchy-Schwarz:
4.4. major term estimate
4.5. estimate the contribution of area which is not filled
\newpage
5. Entropy dcrement argument
\newpage
6. Correlation with nilsequences
I wish to establish the following estimate: is the liouville function we wish the following estimate is true.
Where we have as ,
is a compact space.
I do not know how to prove this but this is result is valuable to consider, because by a Fourier identity we could transform the difficulty of (log average) Chowla conjecture to this type of result.
There is some clue to show this type of result could be true, the first one is the result established by Matomaki and Raziwill in 2015:
Theorem 8 (multiplication function in short interval)
is a multiplicative function, i.e. . as , then we have the following result,
And there also exists the result which could be established by Vinagrodov estimate and B-S-Z critation :
Theorem 9 (correlation of multiplication function and nil-sequences in long interval)
is a multiplicative function, i.e. . is a polynomial function then we have the following result,
\newpage {9} \bibitem{Sarnak} Peter Sarnak, Mobius Randomness and Dynamics.
\texttt{https://publications.ias.edu/sites/default/files/Mahler }. \bibitem{Laudau} JA 虂NOS PINTZ (BUDAPEST). LANDAU鈥橲 PROBLEMS ON PRIMES.
\texttt{https://users.renyi.hu/~pintz/pjapr.pdf} \bibitem{BSZ} Knuth: Computers and Typesetting,
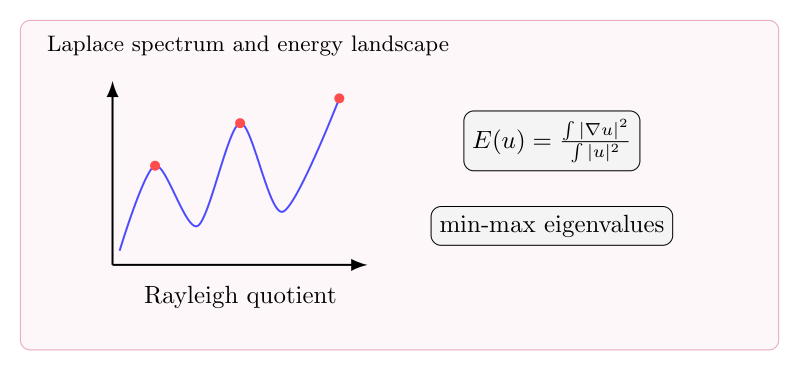
The story of the infinite dimensional space of $\Delta$ is following, we eliminate ourself with compact smooth non-boundary manifold $M$ with metric $g$, then we have Betrami-Laplace operator $\Delta_g$. We could instead $\Delta_g$ by hodge laplace $dd^*+d^*d$, but let we consider $\Delta_g$ the eigenvalue problem:
$$\Delta_g u=\lambda u$$
A classical way to investigate the eigenvalue problem is according to consider variational principle and max-min principle. We equip the path integral on the function space $C^{\infty}(M)$:
$$E(f)=\frac{\int_M |\nabla u|^2}{\int_M |u|^2 }$$
Then it have a sequences of eigenvalue, negative of course: $$0<-\lambda_1<-\lambda_2<…<\lambda_k<…$$
Then things become interesting, the morse theory of infinite space involve, called the infinite space as $X$, so at least, shrink the far place of $X$ as a point, in physics, this mean, cut off at fix scale. And we can take the scale to infinite small, we use the cutoff one to approximation the real one. What I can do is the following, I can proof the eigenvalue function is uniformly distributed in $L^2(M_g)$ (after rescaling of course) and the classical weyl law(although can not give a good error term estimate), but thing become more complicated when I try to consider the infinite space $X_{M_g}$’s topology, at finite scale at least, i.e. $X_{M_g}^{h}$ which is the cut off at scale $h$. Among the other thing, I believe the following issue is true, but without ability to proof it:
>**Problem**
for every manifold $M$ and metric $g$ on $M$, the topology of infinite space $X_{M_g}$ is the same, beside this, the inverse could be true, i.e. If $X_{M_1},X_{M_2}$ is not homomorphism for some scale $h$ then $M_1,M_2$ is not homomorphism.
By intuition, I think it is depend by the underling manifold’s topology. But I do not have a rigorous proof, I definitely have a non-rigorous one, if ignore the coverage…
As I find this problem when I try to give a proof of weyl law, I do not check the reference, may be this problem is a classical one? As always, I will appreciate to any interesting comments and answers, thanks a lots!A
2.
We begin with our favorite situation, the Dirchlet problem on bounded simple-connected domain $\Omega$ in $\mathbb R^n$. Let $\lambda_1$ be the first eigenvalue of $$\Delta u=\lambda u \ in\ \Omega$$
$$u=0\ \ on\ \partial\Omega$$
Rescaling $u$ such that $\sup_{\Omega} u=1$, I think the following property of the first eigenvalue is true.
>**Problem**
We have, the Minkowski functional of $\Omega$, called $M_{\Omega}$ and the Minkowski functional with the ball $B$ such that $vol(B)=vol(\Omega)$, then along the level set of $u$, i.e. the fiber: $$\Omega=\cup_{t\in [0,1]}l_t, l_t:=\{t|x\in \Omega, u(x)=t\}$$
We pretend for the isolate point $l_1$ to be a ball with radius 0, so equipped it with the uniformly density at every direction in $S^1$, i.e. the mass distribution given by $M_B$ and the total mass coincide with the total mass induce by $M_{\Omega}$ in $l_0$, i.e.
$$\int_{e\in S_1}M_{\Omega}(e)d\mu=\int_{e\in S_1}M_{B}(e)d\mu$$
The measure $d\mu$ equipped on $S^1$ is the natural Haar measure. And the cost function is given by $c(x,y)=\|x-y\|^2$. Then, among this setting,
I wish the following property to be true:
Along the direction $1\to 0$, the transport of density $\partial_{t_0} M_{\cup_{t=t_0}^1l_t}$ given the unique optimal transport of the natural measure induce by $M(\Omega)$ and $M(B)$.
**Remark 1** As point out by SebastianGoette, the multiplicity of the first eigenvalue must be one, thanks to the eigenfunction never change the symbol, so we are in the best case.
**Remark 2**:I am not very sure this property could always true, there may be a center example when $\Omega$ is not convex, but I tend to believe it is true at least when $\Omega$ is convex.
**Remark 3**: As point out by Dirk, when you try to consider the optimal transport problem, you always need to point out the cost function $c(x,y)$ defined on $\Omega \times \Omega$, for there, I think the naive choice is $c(x,y)=\|x-y\|^2$
The thing I can proof is the following, the level set of $u$ should be convex by brunn-minkowski inequality, and some type of monotonically property, i.e. more and more like a ball when the level set is more and more shirking smaller form $\partial \Omega$ to the point $f$ arrive maximum.
I will appreciate for any relevant comments and answer, thanks!
 .
 , In general the form is given by,
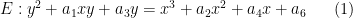
 , then, we have a much more simper form,
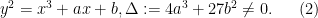

 .
 living in a fix field
 . \paragraph{j-invariant} The first one is by the isomorphism in
 . i.e. we say two elliptic curves
 is equivalent iff

 .
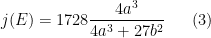
 , all elliptic curve twist with


 , induce by the map
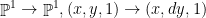 .
 structure} We need a extension of the elliptic curve
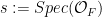 ,
 .
 is regular and minimal, the construction of
 and then blow up.
 is given by the Weierstrass equation with coefficent in
 .

 The weil pairing of
 is given by a unit in cycomotic fields, i.e.
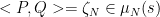
 ? In this case we have a analytic isomorphism:
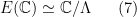
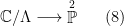

 , and the Weierstrass equation
 . The full n tructure of it is given by
 and the value of

 is induce by


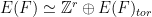
 ,
 is finite.

 ,
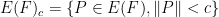 is finite.
 .
 is still very unclear, we have the BSD conjecture, which is far from a fully understanding until now.
 .
 , and a locally value map
 , then we have the short exact sequences,
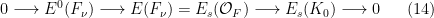
 are union of disc indexed by
 ,
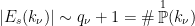
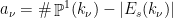 , then we have Hasse principle:

 reduce to count points in
 , reduce to count the Selmer group
 . We have a short exact sequences to explain the issue.

 , there
 such that:


 or
 when
 .
 is a fixed prime, we can consider the Tate module:

 , we know
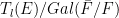 , decompose it into a lots of orbits, so we can define
 , the decomposition group of
 (extension of
 is the inertia group of
 is generated by some Frobenius elements


 .
 is the invariant depending the isogenous class in the follwing meaning:
 isogenous to
 iff
 ,
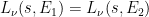 .
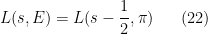
 come from an automorphic representation for
 . Now we give the statement of BSD onjecture.
 is the regulator of
 be the volume of
 Then we have,
 .
 .

 is an explictly positive integer depending only on
 for
 .


 but not 1? if it is 1, then the action
 distribute is not trasitive on
 .

 . So how to investigate
 ? We can look at the action of it on something, for particular, we look at the action of it on Riemann sphere, i.e.
 given by fraction linear map:
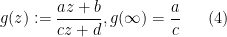
 and the algebraic primitive theorem. Due to I always looks the fraction linear map as something induce by the permutation of the roots of polynomial of degree 2, this is true at least for fix points, and could natural extension. So how about the higher dimension generate? consider the transform of
 tuples induce by polynomial with degree
 ?
 , then
 action faithful on
 , i.e. except identity, every action is nontrivial. This is easy to be proved, observed,

 is invariant under the action of
 , i.e.
 ,
 . The proof is following,

 or the same,
 . All the argument for
 make sense for

 , define,

 is the kernel of map
 , i.e. we have short exact sequences,
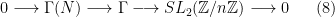
 is just like
 .
 is called a congruence group iff
 ,
 .
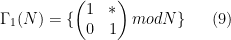
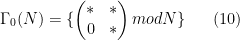
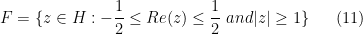


 .
 .

 , but this is very natural to get a modification to a right one.
 are
 and
 or if
 on the unit circle and

 , then
 expect in the following three case:
 if
 .
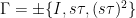 if
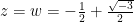 .
 if
 .
 .
 is generated by the two elements
 ,
 . But not free group, we have relationship
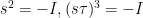 .
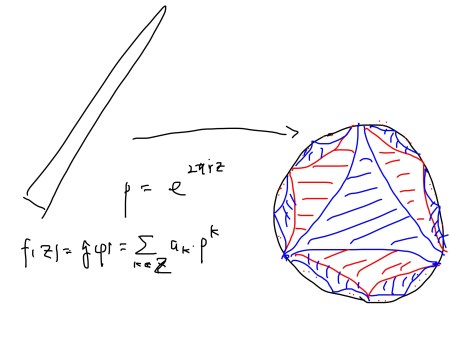
 , it has a
 -expension,

 .


 .

 , which is too big. But fortunately we can use the symmetry of hyperbola to improve the error term.


 denotes a polynomial of degree
 .
 is the residue of
 at
 .


 is the central point under the hyperbola.
 .
 .
 .

 and then integral it. This end the proof. For general
 , the story is the same, by induction.
 .


 , it is known that
 is not right.
 , is there a asymptotic formula for
 ?
 is a polynomial with degree
 ?
 is a polynomial with degree
 ?


 ,
 .


 , by combining the theorem


 is the volume of the unit ball in
 . Langrange proved that every natural number can be represented as the sum of four squares, i.e.
 , and Jacobi established the exact formula for the number of representations


 as the additive convolution of
 and
 , i.e.

 squares by integration.

 in
 ), indeed for
 we have
 if
 ) and the sphere (
 ).

 is a irreducible polynomial. And for each prime
 , let
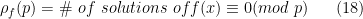
 .

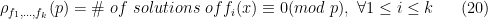

 . We know
 is solvable iff
 or
 . One side is easy, just by Fermat little theorem, the other hand need Fermat descent procedure, which of course could be done by Willson theorem. In this case,

 be an algebraic number field, i.e. the finite field extension of rational numbers, let

 is a ring, we call it the ring of integer of
 uniquely.
 in
 , and we can define the norm induce by index.

 .

 , does the exist a asymptotic formula,


 is different prime ideal in
 ? For the question, there is a satisfied answer.

 is some algebraic number, which’s minor polynomial
 , factorize it in the polynomial ring
 ,

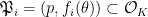 . Then apart from finite many primes, we have,

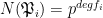 .
 of ideals of
 equal to,

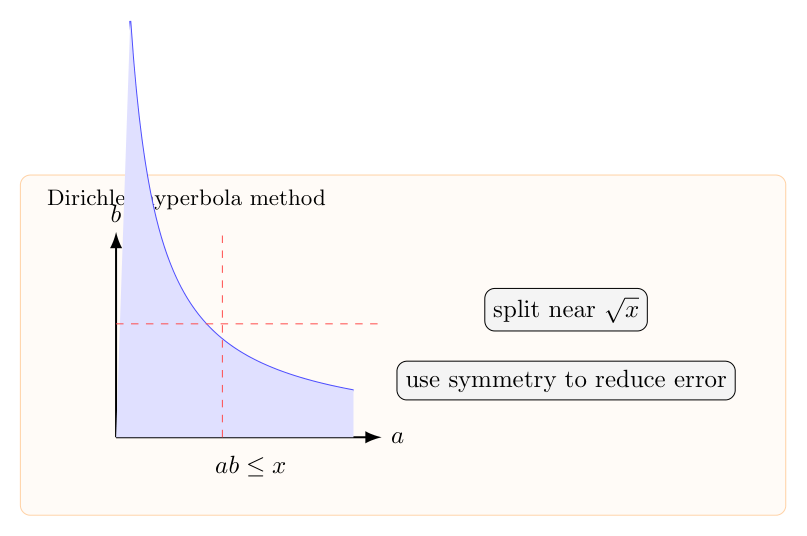
 is a irrational number, we have infinity rational number
 such that:
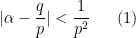
 , the best constant in the suitable sense for the theorem
 and arrive by
 at least. The strategy of the proof of the best constant version involve the Frey sequences.
 and two finite sets
 , set
 , if we have a map:

 such that there exist at least two element
 ,
 .
 , the sequences
 , then
 . Divide
 in an average way to
 . Then the linear structure involve (which, in fact play a crucial role in the approach). And the key point is to look at
 and integers.
 ,


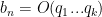 .
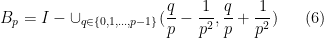
 is very slow, and can be explained by
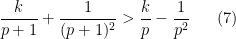
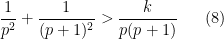
 But in fact they are not really independent, as the number of Bohr sets increase, then you can calculate the correlation, thanks to the harmonic sires increasing very slowly, wwe can get something non trivial by this argument, but it seems not enough to cover the whole theorem


 , and
 . If we can proof,
 , there is a subset
 of
 such that
 .
 , whatever it is, this is not important, the important thing is we can take some ball
 with the center of
 to extension
 to whole space.
 . Then try to find good ball
 is a
 order algebraic number if and only is the minimal polynomial of
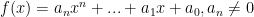 have degree
 .
 , Where
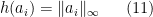
 , there is infinitely
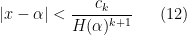
 is a constant only related to

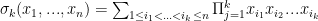 is the
 , what we consider is its inverse,
 , but
 is not smooth, it occur singularity when
 for some
 . And the map, as we know, the singularity depend on the quantity
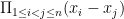 .
 is just the pullback of the canonical metric on
 is a discrete harmonic function on
 if and only if for any
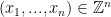 , we have:

 )
 is a discrete harmonic function on
 if and only if for any
 , we have:

 . There exists a constant
 related to
 in
 with radius
 , there is
 portion of points
 satisfied
 . then
 lattices in
 in
 )
 . There exists a constant
 such that, given a discrete harmonic function
 satisfied the condition in
 satisfied
 is the residue one. So
 .
 , we define
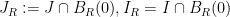 for convenient.
 in

 satisfied
 .
 is connected in
 .
 is a connected compact domain, then there is a function

 . And we have:


 . But this lead to:
 which is contradict to the definition of
 , the cube, you will see, if add one value, then you get every value, i.e. we know the generation space of
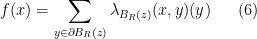
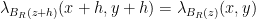 ,
 .
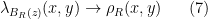
 , So we will gain a lots of identity, These identity carry information which is contract by another argument.
 increasing too fast, exponent increasing by lemma2, but on the other hand, it lie in the integral expresion involve with poisson kernel, but the pertubation of poisson kernel is slow, polynomial rate in fact…
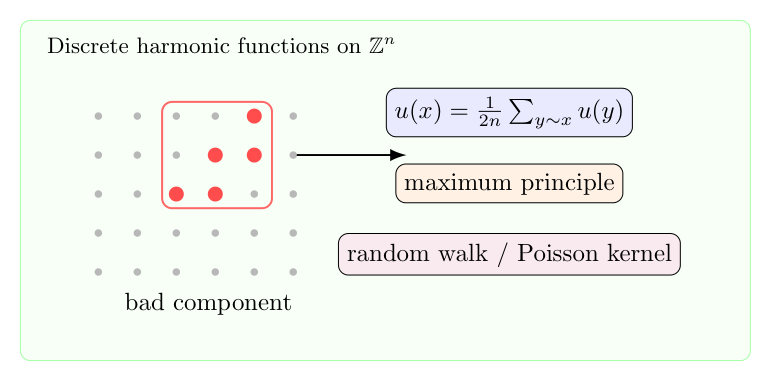
 come from a determination systems
 , where
 ,
 . The correlation of it and the Liuvillou function is 0, i.e. they are orthongonal to each other, more preseicesly it is just to say,
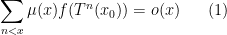
 should be randomness.

 ,
 is orthogonal to Mobius function. due to
 is a basis of
 , suffice to proof,
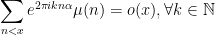
 , and proof that the theorem MR hold we need only to proof it hold for
 instead of

 we have:

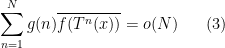
 .

 . We can not get good estimate for all term,
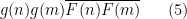


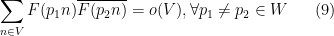

 and trivial inequality

 and then break up
 into
 , this mean,


 in
 , if
 ,
 is uniformly distributed, then

 : Given
 ,
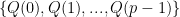 coverages to a uniformly distribution in
 as
 .
 .


 when
 , one has:

 .

 norm, by Chebyschev inequality, this could be control by
 norm, so we only need to establish the following,
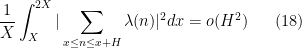
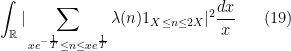
 .
 and
 is to make that
 .
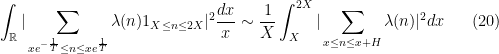
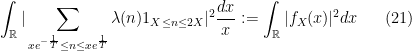
 . Note that,

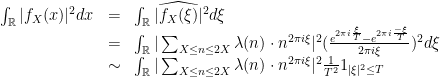
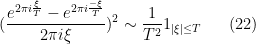


 with additive structure, it could be looked as a lots of wave with the periodic given by primes, so we could do a orthogonal decomposition in the fractional space, try to prove the cutoff is a error term and we get such a monotonically inequality.
 , we have Euler-product formula:

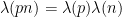 leads to following result:
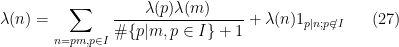
 , but take average at a area which is natural generated and compatible with multiplication, this identity carry a lot of information of the multiplicative property. Which is crucial to get a good estimate for the quality we consider about.
 which is carefully chosen. And we do not consider [X,2X] with linear structure anymore , instead reconsider the decomposition:

 it equipped with a bilinear structure. And
 is a very small set,
 which is in fact have much better estimate.

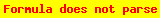
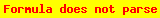


 as
 ,

 is a multiplicative function, i.e.
 .
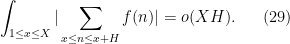
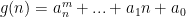 is a polynomial function then we have the following result,